A chatbot that shows its work, in an industry where trust is the product.
Ingest. Retrieve. Answer.
Ingest
Agency staff upload policy PDFs or point Bindery at a carrier page. Documents are chunked and embedded on the server with a local model; no API cost, nothing leaves the stack.
Retrieve
Every question runs hybrid retrieval: semantic vector search and keyword search, fused with reciprocal rank fusion. Below a confidence floor, Bindery abstains instead of guessing.
Answer
Claude writes from the retrieved passages only. Answers stream in live, cite their sources, and suggest the natural next question so the conversation drives itself.
Built the way production AI
should be built.
Retrieval you can watch
Every answer carries a “How I found this” panel: the exact passages retrieved, their similarity scores, and whether semantic search, keyword search, or both surfaced them. The black box, opened.
Streams like a real product
No spinner theater. The interface narrates the actual pipeline (searching documents, reading sources, writing) and the answer types itself in token by token.
Says “I don’t know” on purpose
When retrieval confidence falls below a tuned floor, Bindery declines honestly and points to the agent, without spending a cent on generation. In a regulated industry, refusing well is a feature.
Compliance is architectural
Bindery never recommends a policy, never judges a claim, never gives advice. Claims and disputes trigger an escalation card to a licensed agent. A terms gate runs before the first question.
Measured, not vibes
A golden-set eval harness with an LLM judge scores retrieval recall, faithfulness, and correctness on every pipeline change. The before-and-after reports ship with the repo.
Built for many agencies
Multi-tenant isolation from day one: every document, chunk, and query is scoped to an agency. Staff manage the knowledge base from an admin panel; ingestion is token-gated.
Every pipeline change is scored
before it ships.
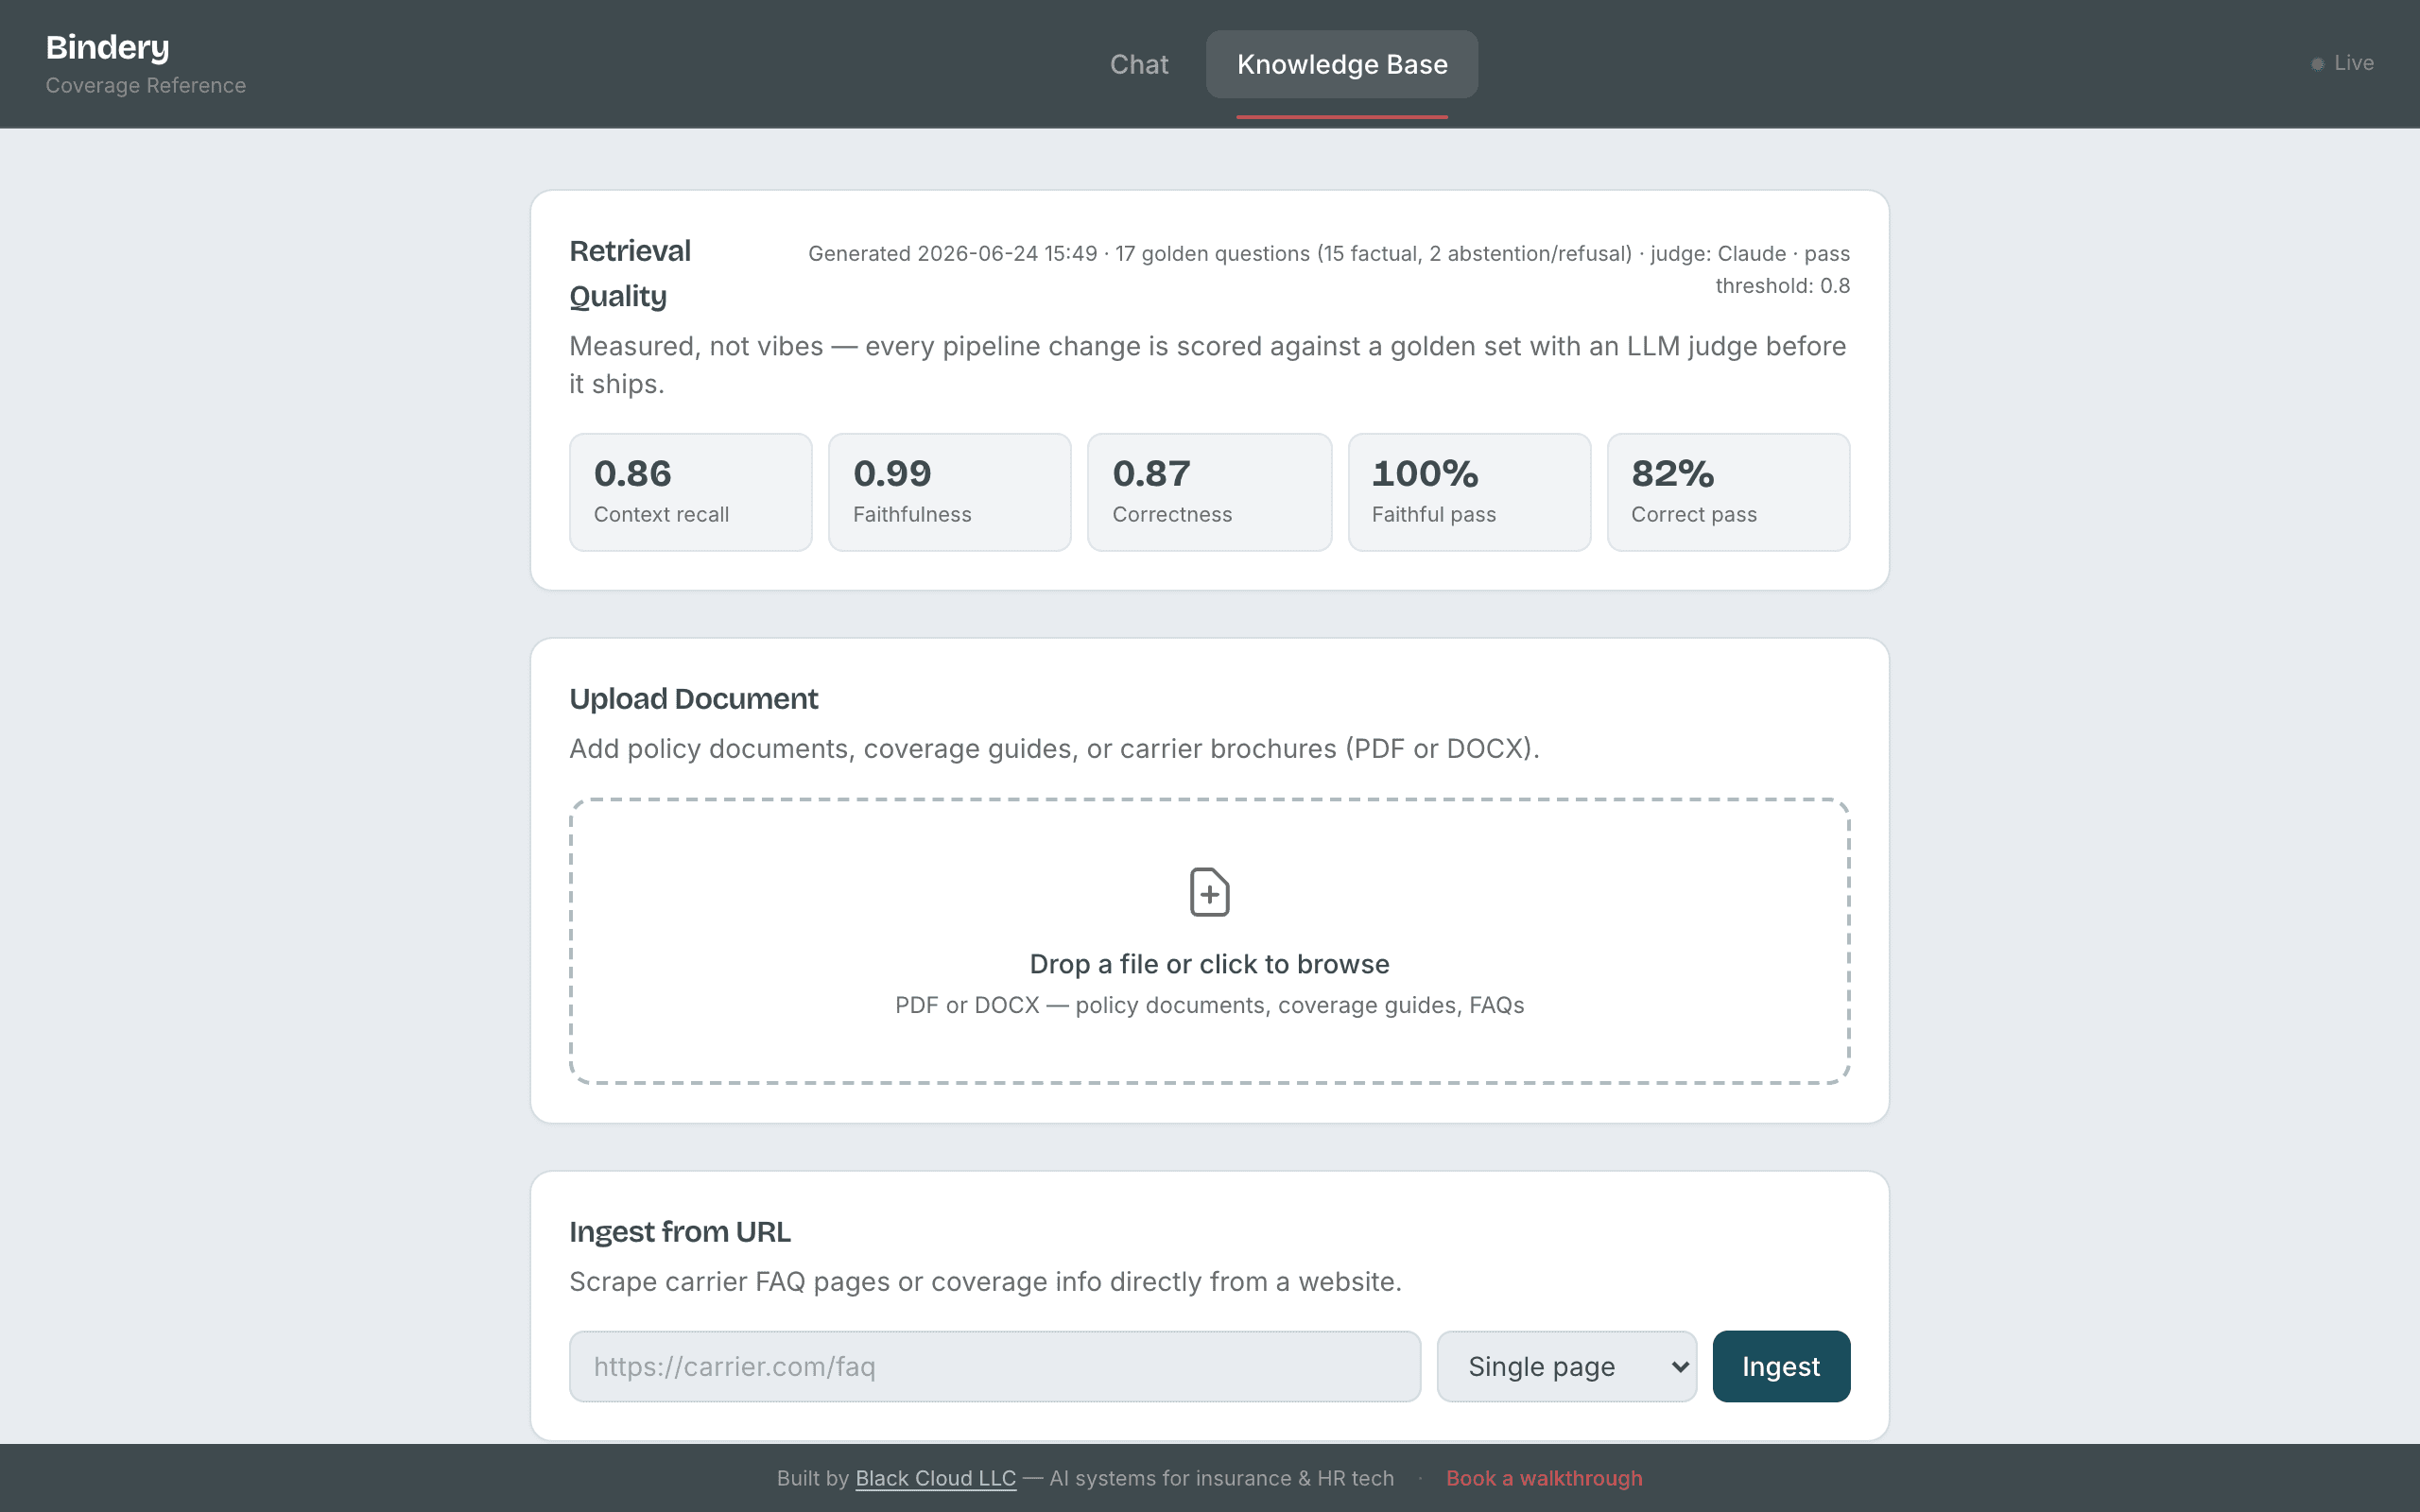
A 17-question golden set runs against the real pipeline, judged by Claude for retrieval recall, faithfulness to the retrieved context, and answer correctness. The retrieval fix that lifted recall from 0.72 to 0.86 shipped with its before-and-after report.
The agency runs it without a tech team.
Staff drop in policy PDFs or paste a carrier URL, and the knowledge base updates itself: chunked, embedded, and searchable in minutes. The same panel shows the eval scores, so quality is a dashboard, not a promise.
Local embeddings keep marginal cost near half a cent per answered question. The whole demo stack carries for under $20 a month.
Under the hood
Rate limiting, a daily spend ceiling, agency allowlisting, and a fail-closed admin gate are in the codebase, not the roadmap. The same architecture drops onto an agency’s existing site as an embedded widget.